This project proposes the creation of an Alternate Reality Game (ARG) entitled DREAMER, aimed at educating the general public about media. Designed as a playful, transmedia, and participatory experience, this game will utilize engaging mechanics (puzzles, false leads, realistic fictional content, urban or digital exploration) in order to develop participants’ critical skills regarding the media. From a narrative perspective, the game will build a fictional universe based on Namur folklore, thereby promoting the latter while linking playful content with real cultural points of interest in this geographic area.

This PhD project will provide diversity-based sampling techniques for the analysis and test of variability-aware Cyber-Physical Systems (CPSs). In particular, we will explore 1) formal modelling of the variability space of CPSs, 2) Exploring the notion of diversity, and 3) designing novel diversity-based algorithms. The contributions will be evaluated on a diversity of CPSs including space satellites.

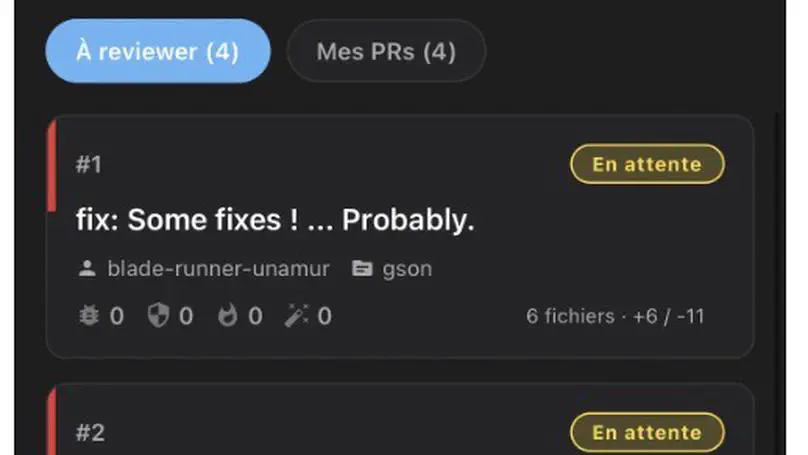
Code review is a key practice in modern software development, yet it remains largely confined to desktop workstations. This thesis focuses on designing a code review environment suited to mobile devices (smartphones and tablets) where reading and navigating source code is particularly challenging. We first survey the state of the art in static code analysis tools (SonarQube, CodeScene), software visualization techniques (CodeCity, Sankey diagrams, dependency graphs), and mobile ergonomics. Based on these findings, we propose several code visualization methods tailored for small screens and implement them in a mobile application prototype called Blade Runner, which interfaces with the GitHub API. The proposed methods are evaluated with users to assess their relevance for mobile code review.

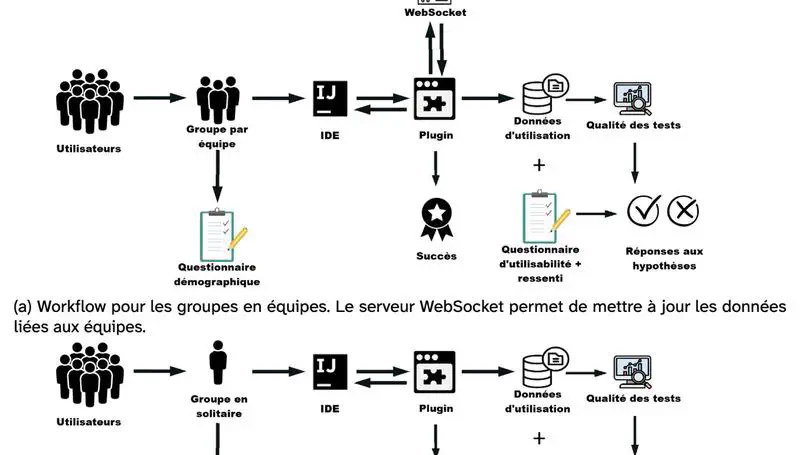
It stems from Berg’s Ber25 study, which lacks information on cooperation in gamified software testing education. This avenue is therefore being explored in the current master thesis. Following a literature review of testing, gamification, and cooperation, cooperation was fostered through interdependence among team members, and selected game elements are achievements. The IntelliGame plugin, in Berg’s modified version, was reused and adapted to meet the current requirement. An experiment was carried out to test the effects of cooperative gamification on students’ performance and motivation. During this experiment, students were split into two groups : one with gamified cooperation and the other without. The sample size did not permit statistically significant results. Nevertheless, it seems that students in the non-cooperative group performed slightly better. These results might have been impaired by a bug that occurred during the experiment and that impacted the group more severely in cooperative settings.
Researchers and practitioners have developed automated test case generators for various languages and platforms, each with different strengths. Comparing these tools requires large-scale empirical evaluations, which demand significant setup and analysis. The JUnit Generation benchmarking infrastructure (JUGE) automates the production and comparison of Java unit tests for multiple purposes, aiming to streamline evaluation, support knowledge transfer, and standardize practices. This master’s thesis will use the existing JUGE infrastructure to conduct an extensive empirical comparison of unit test generators for Java, and provide the resulting dataset to the research community.
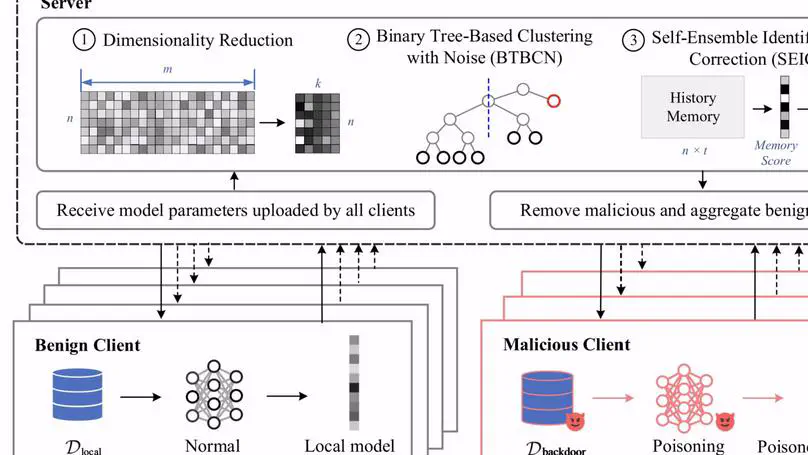
Federated learning trains a shared model without collecting the data, which also exposes it to poisoning: a malicious client can corrupt the global model through the updates it sends. This thesis replicates FedDMC (IEEE TDSC 2024), a detection defense, from the code its paper designates, on MNIST, against four poisoning attacks and three baseline defenses. The published detection can be reproduced, but only after a correction the paper never mentions: the released code trains with the Adam optimizer, and that undocumented default silently breaks detection for two of the four attacks. However, with the SGD optimizer described in the paper, detection is perfect on all four attacks. The replication also documents further gaps between paper and code (a broken data-split flag, swapped metric labels, a different default clustering method), and shows the released baselines are simplified versions of the published methods, so the paper’s comparison cannot be checked from its own artifact. The logs from all 82 complete runs are public in a replication package. The general lesson is that a published defense result needs to be verified by an independent replication before it can be trusted.